OpenAI introduced GPT-6 Cyber on November 5, 2026 as a specialized version of GPT-6 Astra for authorized vulnerability discovery, exploit development and web penetration testing. This is not a routine ChatGPT model launch. Access begins with a small group of vetted organizations, and OpenAI classifies the model at the Critical capability level for cybersecurity.
The announcement combines striking benchmark results with unusually strict deployment controls. GPT-6 Cyber reaches 48.5% on ExploitGym, has a published 1.05-million-token context window, and costs $20 per million input tokens and $100 per million output tokens at the standard short-context rate. Yet an organization still needs Daybreak Red approval before it can send a request.
For security leaders, the practical question is not whether the model can write code. It is whether the organization can isolate targets, prove authorization, protect credentials, review generated exploits and reproduce every finding before it reaches production. For everyone else, the key point is simpler: GPT-6 Cyber is not a consumer upgrade and does not appear in a normal ChatGPT model picker.
GPT-6 Cyber at a glance
- Announced: November 5, 2026.
- Model ID: gpt-6-cyber.
- Access: approved organizations with Daybreak Red access; OpenAI says an account team confirms eligibility.
- Context window: 1,050,000 tokens, with up to 128,000 output tokens.
- Standard short-context price: $20 per million input tokens, $2 per million cached input tokens, $25 per million cache-write tokens and $100 per million output tokens.
- Primary use: authorized vulnerability research, exploit reproduction, web penetration testing and fix verification.
- Safety classification: Critical for cybersecurity in OpenAI’s deployment framework.
The listed price is a model rate, not a complete project budget. Long-running security work can also consume tool calls, repeated context, cache writes, test infrastructure, analyst review and remediation time. Approved organizations may have custom rate limits or commercial terms.
What GPT-6 Cyber is built to do
GPT-6 Cyber is a cyber-specialized GPT-6 Astra variant. OpenAI describes three core jobs: investigate a vulnerability, reproduce it in an authorized test environment and verify that a fix works. The model page supports text input and output, image input, reasoning, structured outputs, function calling and tools including web search, hosted shell, computer use and MCP. Fine-tuning is not listed as supported.
Those tools make the system more than a code-completion model. A security workflow can inspect a repository, launch a controlled service, exercise an attack path, examine a crash, propose a patch and run a regression test. The same chain is also why access is restricted. A model that can connect evidence across a million-token context and operate tools needs stronger controls than a passive chatbot.
What the benchmarks actually measure
OpenAI reports 48.5% on ExploitGym, compared with 32.1% for GPT-5.6 Cyber. That is a 16.4-percentage-point improvement, or about 51% relative improvement. ExploitGym evaluates exploit-development work in prepared environments; it does not measure whether the model can or should attack an arbitrary real system.
On OpenAI’s web penetration-testing evaluation, GPT-6 Cyber reached 40.3% recall, compared with 32.0% for GPT-6 Astra. Recall measures how many expected findings the system surfaces. It does not by itself establish precision, severity, business impact or whether a report is ready to hand to an engineering team.
RemoteExploitBench illustrates the capability-policy split. OpenAI says GPT-6 Cyber completed 95% of the evaluated tasks, while GPT-6 Astra deployed with Daybreak Blue refused 100% of those requests. That comparison is not simply a model leaderboard. It shows that the deployment tier and its policy can deliberately limit what otherwise capable systems will do.
How to read vendor-produced evaluations
All of these headline results come from OpenAI’s own launch materials and safety evaluation. That does not make them uninformative, but it does shape how they should be used. The company selected the model configuration, test harness, tools and reporting method. Independent researchers have not yet had broad access to repeat the full set of measurements, and a restricted model may remain difficult to compare under identical conditions.
A careful buyer should ask for the task definition, number of attempts, tool permissions, time budget, scoring rules and failure categories. A strong average can conceal uneven performance across languages, platforms or vulnerability classes. Internal evaluation should begin with representative repositories and known findings, include negative controls, measure false positives and record the analyst time required to validate each result. The goal is not to recreate a leaderboard; it is to determine whether the model improves the organization’s own defensive workflow without introducing unacceptable risk.
The real-world findings are significant but need careful wording
OpenAI says it used GPT-6 Cyber to develop 948 Linux privilege-escalation exploits and to identify 81 previously unknown high-severity vulnerabilities in Firefox. The Linux figure refers to working exploits developed during the research program, not 948 newly discovered Linux vulnerabilities. OpenAI says Mozilla released fixes for many of the Firefox issues.
These results are evidence that an advanced model can accelerate legitimate vulnerability work. They are not evidence that every generated exploit is novel, reliable or safe to run. Real systems differ in build options, mitigations, dependencies and legal scope. Teams should reproduce findings in an isolated environment, preserve logs and require a qualified reviewer before disclosure or remediation.
Why the Critical rating matters
“Critical” describes OpenAI’s assessment of cyber capability, not a recommendation that the model is suitable for unsupervised use. The system card gives GPT-6 Cyber the same high-level deployment designations as GPT-6 Astra: Critical for cybersecurity, High for biological and chemical capability, and below High for AI self-improvement.
OpenAI also reports 99.93% out-of-scope avoidance without a deployment prompt and 100% with the deployment prompt on its alignment evaluation. Those numbers are encouraging within the tested distribution, but no benchmark can prove that a model will handle every ambiguous authorization claim, novel prompt injection or multi-step tool interaction correctly.
The safer reading is that GPT-6 Cyber combines high capability with layered controls. OpenAI says new safeguards are intended to block high-risk activity against critical systems and assistance that would enable high-risk activity. Signals of suspicious use can trigger temporary limitations or review, and legitimate research can occasionally be flagged.
Daybreak Blue and Daybreak Red are different access paths
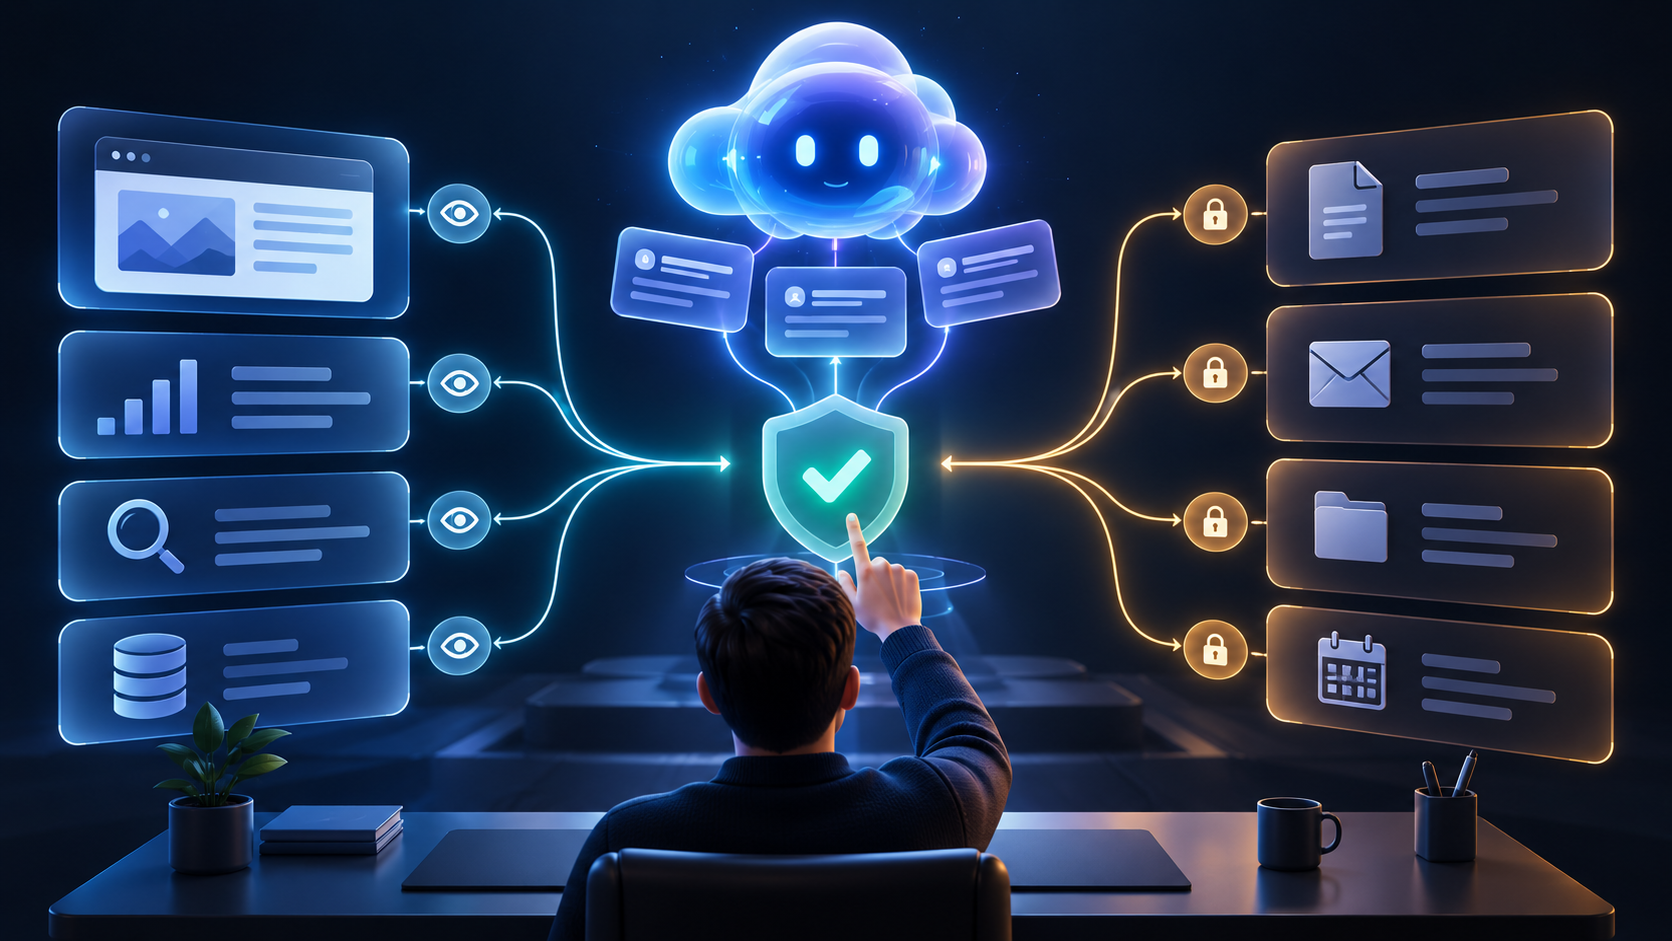
Daybreak Blue is OpenAI’s program for verified defenders using advanced cyber capabilities under a more restrictive policy. Daybreak Red is the path for deeper authorized exploit development and testing. GPT-6 Cyber requires Daybreak Red approval; joining a general API plan or paying the token price is not enough.
The system card says approval can involve identity verification, use restrictions and organizational security requirements. Examples include single sign-on, multi-factor authentication and API IP allowlisting. Zero Data Retention API customers generally need Private Safety Processing so automated safety review can still operate without using the ordinary retention path.
Organizations should expect the access decision to evaluate who will use the model, which assets they are authorized to test, how credentials are protected, where tool execution occurs, how logs are reviewed and what happens when a request crosses policy. A claimed security purpose does not remove the need for documented authorization.
Pricing and context limits
OpenAI’s model page lists standard short-context rates per one million tokens: $20 for input, $2 for cached input, $25 for cache writes and $100 for output. Short-context cache writes cost $25 per million tokens for 30 minutes or $50 per million for 12 hours. A workload using one million new input tokens and 100,000 output tokens would therefore have a published model charge of $30 before cache writes, tools or other services.
The 1.05-million-token context window can accommodate large repositories, logs and test artifacts, while the 128,000-token output ceiling supports long reports or patches. Capacity is not the same as relevance. Feeding an entire repository can raise cost, expose unnecessary secrets and make review harder. Curated context, scoped credentials and a reproducible test harness remain better than indiscriminate access.
A safer deployment checklist
- Confirm written authorization for every target, environment and testing window.
- Run exploits only in isolated replicas, disposable labs or purpose-built ranges.
- Use separate service accounts, least-privilege permissions, MFA and IP allowlists.
- Block production credentials and customer data from the model unless explicitly required and approved.
- Record prompts, retrieved files, tool calls, generated code, test outputs and reviewer decisions.
- Require human approval before executing generated exploit code, publishing a disclosure or changing production.
- Re-test fixes independently and keep a rollback path.
Teams should also separate discovery, reproduction and remediation permissions. A model that can identify a suspicious code path does not automatically need permission to exploit a live service. Staged access reduces the blast radius of a wrong assumption and makes the audit trail easier to understand.
What regular ChatGPT users should know
GPT-6 Cyber is an API model for approved organizations, not a general ChatGPT option. Its announcement does not change the model selected in a personal or business ChatGPT account, and the published API price does not buy access by itself. OpenAI directs interested organizations to their account team for confirmation.
Readers should be skeptical of downloads, browser extensions or websites promising instant GPT-6 Cyber access. The official model ID is gpt-6-cyber, and access is tied to an approved organization. A third party asking for cloud credentials or security-tool permissions in exchange for unofficial access presents exactly the kind of supply-chain risk a security team should avoid.
A useful reference for the human reviewer
A model can produce an exploit without teaching the reviewer why it works. Jon Erickson’s Hacking: The Art of Exploitation, 2nd Edition remains a relevant low-level reference for C, memory, networking and exploit mechanics. Verify the edition, format, seller and current price before ordering; the book is educational and does not grant authorization to test systems.
Affiliate disclosure: ReaderSpice may earn a commission from qualifying Amazon purchases made through the link above, at no additional cost to you.
The bottom line
GPT-6 Cyber is one of the clearest signs that frontier AI security work is moving from code review toward end-to-end vulnerability research. Its 48.5% ExploitGym score, 40.3% web-pentesting recall and reported Firefox findings suggest a meaningful capability jump. The million-token context and broad tool support could help vetted teams investigate complex systems that exceed the scope of a short chat.
The restriction is part of the product, not a footnote. Daybreak Red approval, organizational controls, automated safeguards and human review are the conditions under which OpenAI is willing to deploy the model. For most readers, there is nothing to enable. For authorized security organizations, the right first step is to build the isolated, auditable workflow before requesting access.
Sources
OpenAI — Introducing GPT-6 Cyber
OpenAI Deployment Safety Hub — GPT-6 Cyber system card
OpenAI API — GPT-6 Cyber model page, pricing and limits
OpenAI API — Cybersecurity safeguards and access programs
Reuters — OpenAI launches GPT-6 Cyber for a vetted group
No Starch Press — Hacking: The Art of Exploitation, 2nd Edition
Amazon — Hacking: The Art of Exploitation, 2nd Edition, ASIN 1593271441